Data products · 23 Sept 2026 · 5 min read
Public data as a product: a checklist
Public records are free, detailed and hard to use. Turning them into a product means linking, scoring and citing. This is the checklist we use.
Government and regulatory records hold commercial signals that most teams never see. The data is free. It is also spread across many tables, updated on different schedules and written for compliance, not for decisions.
A product built on public data earns its place by doing the work the reader cannot: watching, linking, scoring and citing. This is the checklist we follow.
1. Pick one domain and one source family
Breadth kills these products. One basin and one regulator let us link records into real campaigns. Three regions and five sources would have produced a feed of unrelated changes.
Ask: can a user act on one record from this source today? If yes, the source is worth a pipeline.
Document the source before writing the importer. Record who publishes it, how often it changes, whether old versions remain available and which terms govern reuse. A technically accessible endpoint is not automatically a dependable product dependency.
2. Snapshot, then diff
Take a full copy of each dataset on a schedule. Compare it with the last copy. The changes are the product; the raw tables are not.
Define what counts as a meaningful change before you build. A new permit matters. A corrected typo does not. Users want a filtered feed, not a dump.
Keep the raw snapshot immutable. When parsing or scoring logic changes, the team should be able to reproduce a result from the original input. Without snapshots, every correction becomes a debate about what the source might have contained at the time.
3. Link records into entities people recognise
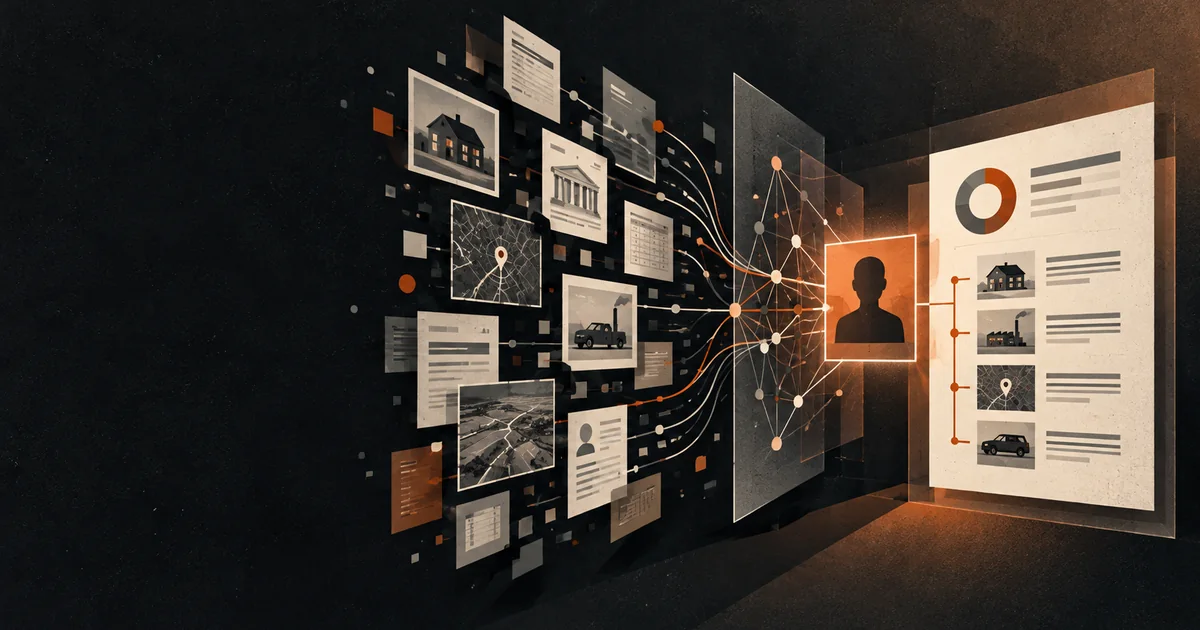
A well, a structure, a lease and an operator are separate rows in separate tables. A business development team thinks in campaigns and accounts. Build the linking layer that turns rows into the thing the user already has a name for.
This step is where most of the engineering time goes, and where most of the value is.
Entity linking needs explicit confidence. Names change, identifiers are reused and ownership moves. Prefer stable source identifiers when they exist, but never assume one field is perfect. Record why two rows were linked and make uncertain matches reviewable instead of silently merging them.
4. Score with inputs the user can see
A score with hidden inputs is an opinion. A score with listed inputs is a tool. Show every factor, give each result a confidence level, and end with a plain decision: watch, investigate or engage.
Start with rules a domain expert can explain. Machine learning may become useful when enough reviewed outcomes exist, but an opaque model cannot compensate for weak source relationships. A transparent baseline is easier to test, sell and improve.
5. Keep facts and inference apart
Every claim in the product is one of two kinds: an observed record with a link to its source, or an inference the product made. Label them differently. Never mix them in one sentence.
Add observation dates to both. A fact can be accurate and still be stale. An inference can be reasonable and still depend on an assumption that has expired. Time is part of provenance.
6. State the limits
Say what the product is not. It is not the authoritative record. A cost estimate is not a contract value. A deadline in a filing is not a commitment. Users trust products that know their edges.
Limits should appear where decisions happen, not only in terms and conditions. Keep them short and specific. The goal is not to protect the product with vague language; it is to help the reader choose the right next verification step.
7. Let the buyer test on one target
Offer a free search and a low-cost single report before any subscription. A team that proves value on one real pursuit will subscribe. A team asked to pay first will not.
The trial should use real data and the same method as the paid product. A polished sample built from hand-picked records proves presentation, not reliability. Let the buyer choose a familiar target and judge whether the product finds something worth acting on.
8. Run it every day
A data product is a service, not a release. The pipeline runs daily, the linking improves, the sources change their formats. Plan for the operations from the first week.
Monitor freshness as a product metric. Alert when a source stops updating, a schema changes, row counts move unexpectedly or a scheduled run misses its window. A green application server means little if yesterday’s data never arrived.
Keep a correction path for knowledgeable users. Domain experts will find edge cases before automated tests do. Capture the record, the proposed correction and the evidence behind it. Review the change, update any derived conclusions and preserve an audit trail.
9. Design the output for a decision
A data feed is rarely the final product. Decide whether the user needs an alert, a ranked list, a one-page brief or an export into an existing workflow. The output should match the speed and consequence of the decision.
Make each result self-explaining. Include the reason it appeared, the most important factors, confidence, observation date and source links. When a result is forwarded outside the application, it should retain enough context to be checked.
10. Price the saved work, not the free input
Public records may be free, but watching, cleaning, joining and explaining them is not. Price the product around the work it removes or the opportunity it reveals. Do not apologise for charging because the source itself is public.
At the same time, avoid claiming ownership over the underlying facts. The defensible value is the maintained pipeline, entity model, decision logic and usable delivery. That is also the part a competitor cannot reproduce by downloading one file.
Public data products are slow to build and hard to copy. That is the business case.